

R-bloggers
R-bloggers is a platform that leverages the content from various documents to provide concise summaries for its audience. The platform serves as a hub for information and insights related to a wide range of topics. By summarizing the content from diverse sources, R-bloggers aims to offer valuable and easily digestible information to its readers. The platform’s summaries are designed to provide a quick overview of the key points and insights covered in the original documents, making it a convenient resource for individuals interested in staying informed about the latest developments in various fields.
 Visit R-bloggers
From a raw spreadsheet to a published data package in a day
On 22 July 2026 at 15:05, I made the first commit to a new repository. It held an empty R package and one Excel workbook with field data from a household waste study in Kampala, Uganda. Three minutes ...
📚 Read more at R-bloggers🔎 Find similar documents

Choosing the size of the calibration set in conformal prediction with ahead::conformalize()
This post explores the impact of the split_prob parameter in the ahead::conformalize() function on the resulting prediction intervals. Continue reading: Choosing the size of the calibration set in con...
📚 Read more at R-bloggers🔎 Find similar documents

Estimate your BAC, now 100% in the browser
Thanks to the awesomeness of webR and Shinylive, the tool I made in back in 2014 to estimate your blood alcohol concentration (BAC) now runs 100% in the browser, no server needed! Try the browser vers...
📚 Read more at R-bloggers🔎 Find similar documents
tsmp Is Back: A Faster, Friendlier Matrix Profile Workflow for R
A new chapter for the Matrix Profile in R For a while, tsmp looked quiet. The project was not standing still, though: the Matrix Profile tools for R have been reorganized around a much clearer split b...
📚 Read more at R-bloggers🔎 Find similar documents

[Statistics] Collinearity in regression
Zhenguo Zhang's Blog https://fortune9.netlify.app/2026/10/16/statistics-collinearity-in-regression/ - library(knitr) library(ggplot2) library(dplyr) library(tidyr) library(broom) Problem When performi...
📚 Read more at R-bloggers🔎 Find similar documents

What is an MCP server?
The Model Context Protocol (MCP) is quietly becoming one of the most useful ideas in AI tooling. Here, we describe what MCP is, why it matters, and how to build an MCP server yourself. MCP is a standa...
📚 Read more at R-bloggers🔎 Find similar documents

Spring 2027 data science training courses: January to June
If you plan to learn R or Python in the new year, book before the end of November. Our spring 2027 data science training courses run from January to June, and early bird pricing on the first one ends ...
📚 Read more at R-bloggers🔎 Find similar documents

Can we trust the correlation coefficient in designed field experiments?
One of the fundamental aims of field experiments is to explorare the relationships between several experimental traits, which have been recorded/measured altogheter for all the experimental units. For...
📚 Read more at R-bloggers🔎 Find similar documents

{brochure}: multipage {shiny} apps, now on CRAN
You can read the original post in its original format on Rtask website by ThinkR here: {brochure}: multipage {shiny} apps, now on CRAN A {shiny} app is a single page: one url, one UI, one server funct...
📚 Read more at R-bloggers🔎 Find similar documents
maestro 1.4.0 adds custom pipeline metrics
The 1.4.0 release of maestro is out, and with it comes the ability to record custom metrics from your pipelines. Execution time and success/failure were already tracked, but there was no good way to a...
📚 Read more at R-bloggers🔎 Find similar documents

Cytometry in R and opportunities to contribute to Bioconductor
Flow cytometry researchers have a growing collection of R and Bioconductor tools available to them. But for someone who is comfortable working with cytometry data and has little programming experience...
📚 Read more at R-bloggers🔎 Find similar documents
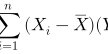
A Trip from Covariance to Correlation and Back
When we have a multi-trait table of data, we might be interested in investigating variability structure and the reciprocal relationships (whether causal or non-causal) among variables. For example, le...
📚 Read more at R-bloggers🔎 Find similar documents