


The AiEdge Newsletter
“The AiEdge Newsletter” provides insights into cutting-edge AI applications at the intersection of edge computing and artificial intelligence. It delves into topics like data augmentation for machine learning, Python programming for web3 and blockchain, and the importance of short-term memory in AI applications. The newsletter explores the challenges of enterprise RAG implementations and the need for intelligent systems that go beyond simple data retrieval. With a focus on practical tools and techniques, it offers a comprehensive guide to leveraging AI technologies for real-world applications. Stay informed about the latest advancements in AI and edge computing with “The AiEdge Newsletter.”
 Visit The AiEdge Newsletter

How Astra Edited Qwen’s Weights
From diagnosing repetitive reasoning to a persistent patch, and what the results establish about weight-space programming.
📚 Read more at The AiEdge Newsletter🔎 Find similar documents

How LLM Distillation Trains Smaller Models
From teacher-written answers to probability targets and feedback on the student’s own output.
📚 Read more at The AiEdge Newsletter🔎 Find similar documents

How Quantization Compresses LLMs
Follow GPTQ, AWQ, and SmoothQuant through weight compensation, channel scaling, and low-precision execution.
📚 Read more at The AiEdge Newsletter🔎 Find similar documents

How CUDA Graphs Speed Up LLM Inference
Replay GPU operations with fresh tokens, growing caches, and changing batches.
📚 Read more at The AiEdge Newsletter🔎 Find similar documents
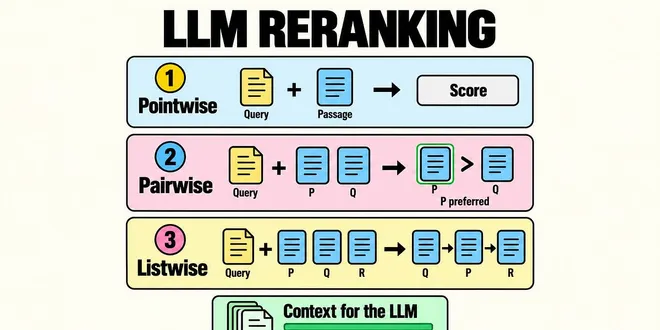
How LLM Rerankers Order Retrieved Passages
Follow pointwise scores, pairwise preferences, and listwise windows from model judgment to useful context.
📚 Read more at The AiEdge Newsletter🔎 Find similar documents

How Looped Transformers Reuse Their Weights
Follow changing attention states, shared gradients, and the real cost of extra passes.
📚 Read more at The AiEdge Newsletter🔎 Find similar documents

How the KV Cache Shapes AI Agent Costs
Why shrinking the cache, reusing a prefix, and keeping it nearby save different resources.
📚 Read more at The AiEdge Newsletter🔎 Find similar documents
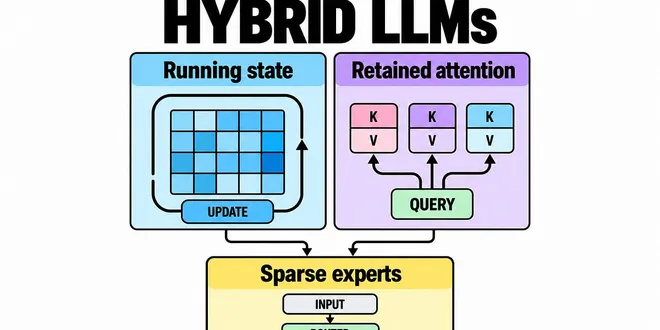
How Hybrid LLMs Combine Memory, Attention, and Experts
Follow Mamba-2, Gated DeltaNet and KDA from state updates to the costs that active parameter counts miss.
📚 Read more at The AiEdge Newsletter🔎 Find similar documents

How Persistent Agents Keep Working
Reconstruct a coding task’s context, preserve accepted work, and recover safely when a worker disappears.
📚 Read more at The AiEdge Newsletter🔎 Find similar documents
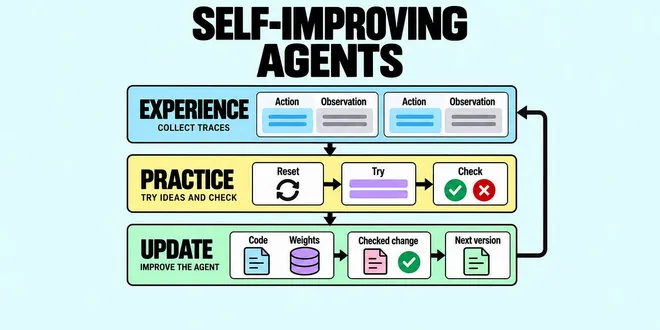
How Self-Improving Agents Learn from Experience
How executable tasks and adaptive curricula turn production failures into useful practice.
📚 Read more at The AiEdge Newsletter🔎 Find similar documents
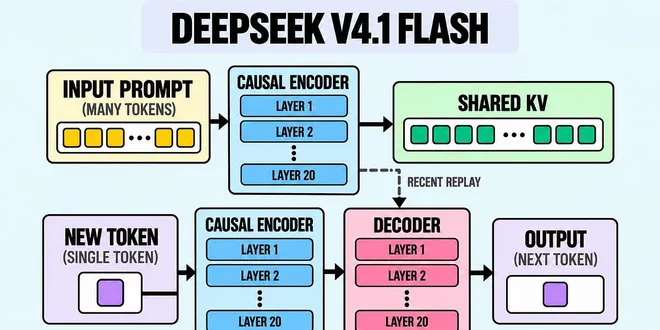
How DeepSeek V4.1 Flash Separates Reading and Generation
How a shorter input path, shared attention memory, and selective reconstruction change the cost of long conversations.
📚 Read more at The AiEdge Newsletter🔎 Find similar documents
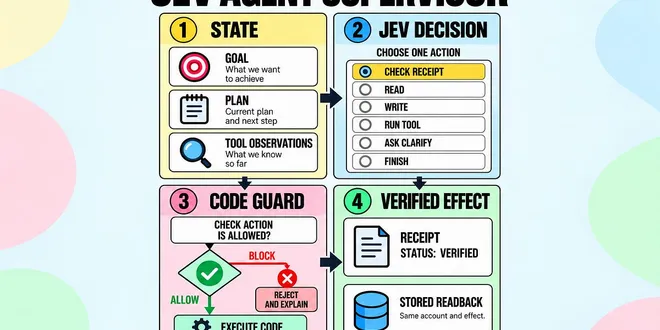
Build a Jev-Supervised AI Agent
Typed decisions, guarded tools, and a measured comparison with LLM supervisors
📚 Read more at The AiEdge Newsletter🔎 Find similar documents